Claude Certified Architect Professional CCAR-P Exam Questions
Preparing for the CCAR-P exam is simple with ITPrepCerts. We offer easy-to-understand study materials that help you learn the most important exam topics. You can study using our PDF questions, practice online with a real exam-style test, or use the desktop practice software. Choose the study method that works best for you and prepare at your own pace.
At ITPrepCerts, we keep our CCAR-P practice questions up to date. Whenever the exam syllabus or objectives change, we update our study materials so you always learn the latest topics. This helps you save time, avoid outdated content, and feel more confident when you take your exam.
You are transitioning a Claude-based deployment from design into implementation.
Which handoff package most directly supports a clean transition?
Correct Answer: C
Option C provides the minimum coherent package required to move from architectural intent to implementable and supportable delivery. The architecture overview establishes system boundaries and component relationships. Architecture Decision Records preserve the context and trade-offs behind key choices. Component contracts define interfaces, schemas, responsibilities, failure behavior, and integration assumptions.
The evaluation framework and reference set allow the implementation team to confirm that prompts, models, retrieval components, and tool integrations continue to meet the defined quality, safety, latency, and cost thresholds. Runbooks translate operational knowledge into repeatable procedures, while the on-call playbook defines detection, escalation, containment, and recovery actions. The known-limitations register prevents unsupported behavior from being mistaken for an implementation defect and helps stakeholders manage residual risk.
Options A and B depend excessively on slides or undocumented verbal knowledge. Option D provides implementation material without explaining the system-level decisions, operating model, acceptance criteria, or limitations. Source code cannot substitute for architectural and operational documentation.
A clean transition does not mean the architect can never be consulted. It means routine implementation and support do not depend on undocumented knowledge held by a single individual.
Study Guide references/topics: Design-to-implementation handoff; ADRs; component contracts; reference evaluations; runbooks; operational playbooks; limitations management.
===============
A business sponsor has requested an AI solution to “improve customer experience.” The sponsor cannot articulate which customer journey is failing, which metric reflects the failure, or which decisions the AI should support. The sponsor is asking you to begin design work next week.
Which delegation-competency action should you take first?
Correct Answer: D
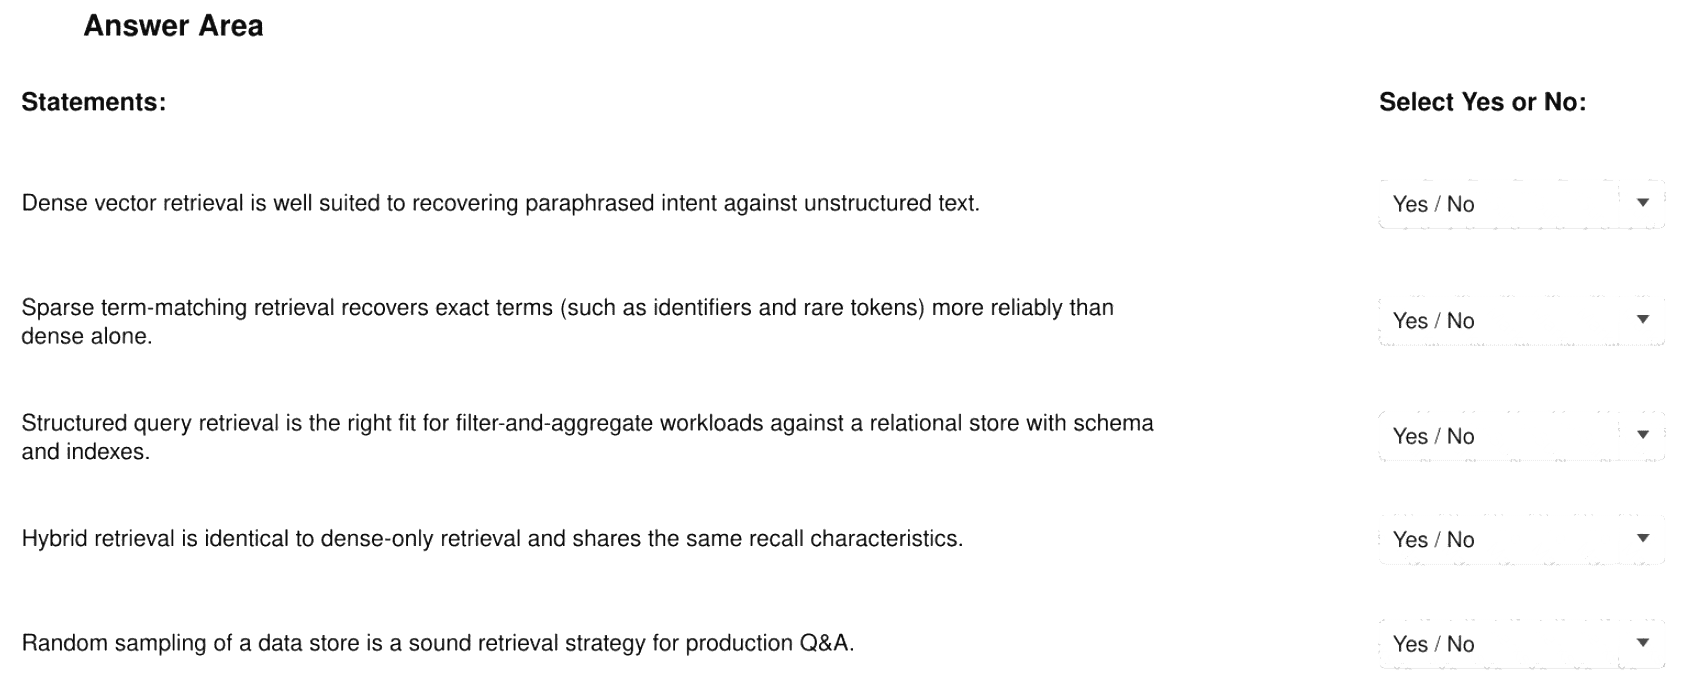
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.
Answer
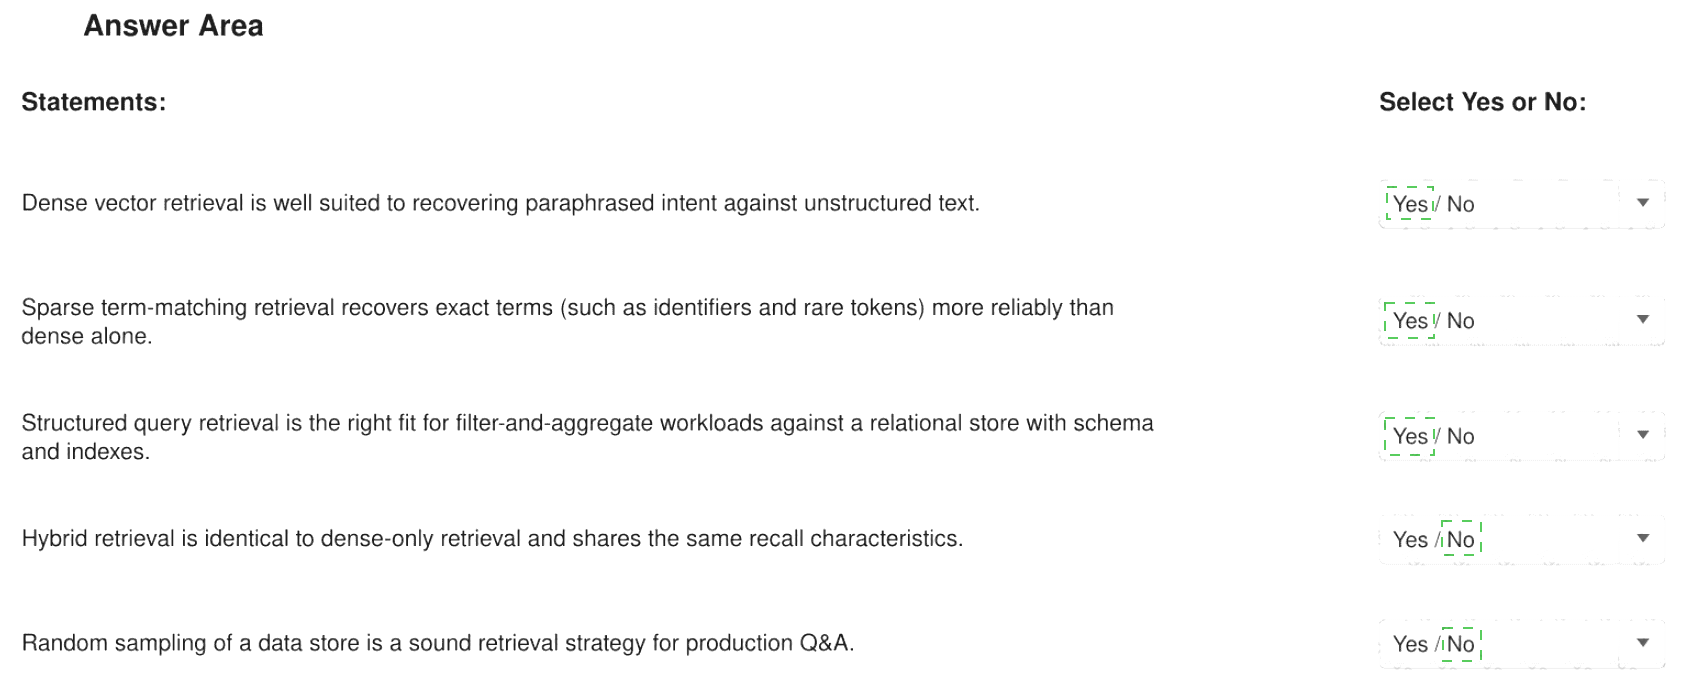
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic’s contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook
Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
===============
You are building an ethics-review checklist for deployments supported by artificial intelligence.
Which two checks belong on the list? (Select two.)
Each correct answer presents a complete solution.
Correct Answer: B, C
An ethics review must examine unsupported generalizations, stereotyping, disparate treatment, and other conclusions about people that are not justified by the evidence. It must also preserve identifiable human accountability for consequential decisions; responsibility cannot be transferred to a probabilistic system. Licensing is a legal and commercial-control question, while latency and throughput are operational requirements. Both remain important, but neither is the central ethical test presented here. Restricting review to low-confidence or threshold-triggering outputs is also inadequate because models can express harmful or biased conclusions with high confidence. Ethical review should cover representative populations, protected and intersectional groups, high-impact outcomes, override mechanisms, transparency, and channels for challenge or appeal.
Study Guide references/topics: Bias and unsupported generalization; human accountability; consequential decisions; ethical oversight.
A Claude architect is auditing configuration scope assignments.
Which two statements correctly identify an appropriate use of user-scope configuration versus other scopes? (Select two.)
Correct Answer: A, B
User scope applies to one engineer across every project and is therefore appropriate for portable personal preferences. Option A fits this definition because an interface theme belongs to the individual rather than to a repository or organization. Option B also fits because Claude Code provides a language setting for the preferred response language, and placing that preference in user scope makes it apply across repositories.
Option C requires managed configuration because an organization-wide security control must be centrally deployed and resistant to individual override. Option D belongs in project scope because repository-specific MCP endpoints must be shared consistently with that repository’s contributors.
Option E describes credential handling rather than merely a preference assignment. Credentials must not be placed in a repository, but avoiding version control alone is insufficient. They must be stored through a supported secure authentication mechanism, protected environment configuration, operating-system credential facility, or approved secrets manager—not inserted as plaintext into an ordinary settings file.
Anthropic defines user scope as affecting one user across all projects, project scope as shared repository configuration, and managed scope as the location for enforceable organizational controls. It also explicitly lists themes and other personal settings as user-scope use cases. Claude Code Configuration Scopes
Study Guide references/topics: User scope; project scope; managed configuration; personal preferences; repository-shared MCP configuration; credential protection.
===============